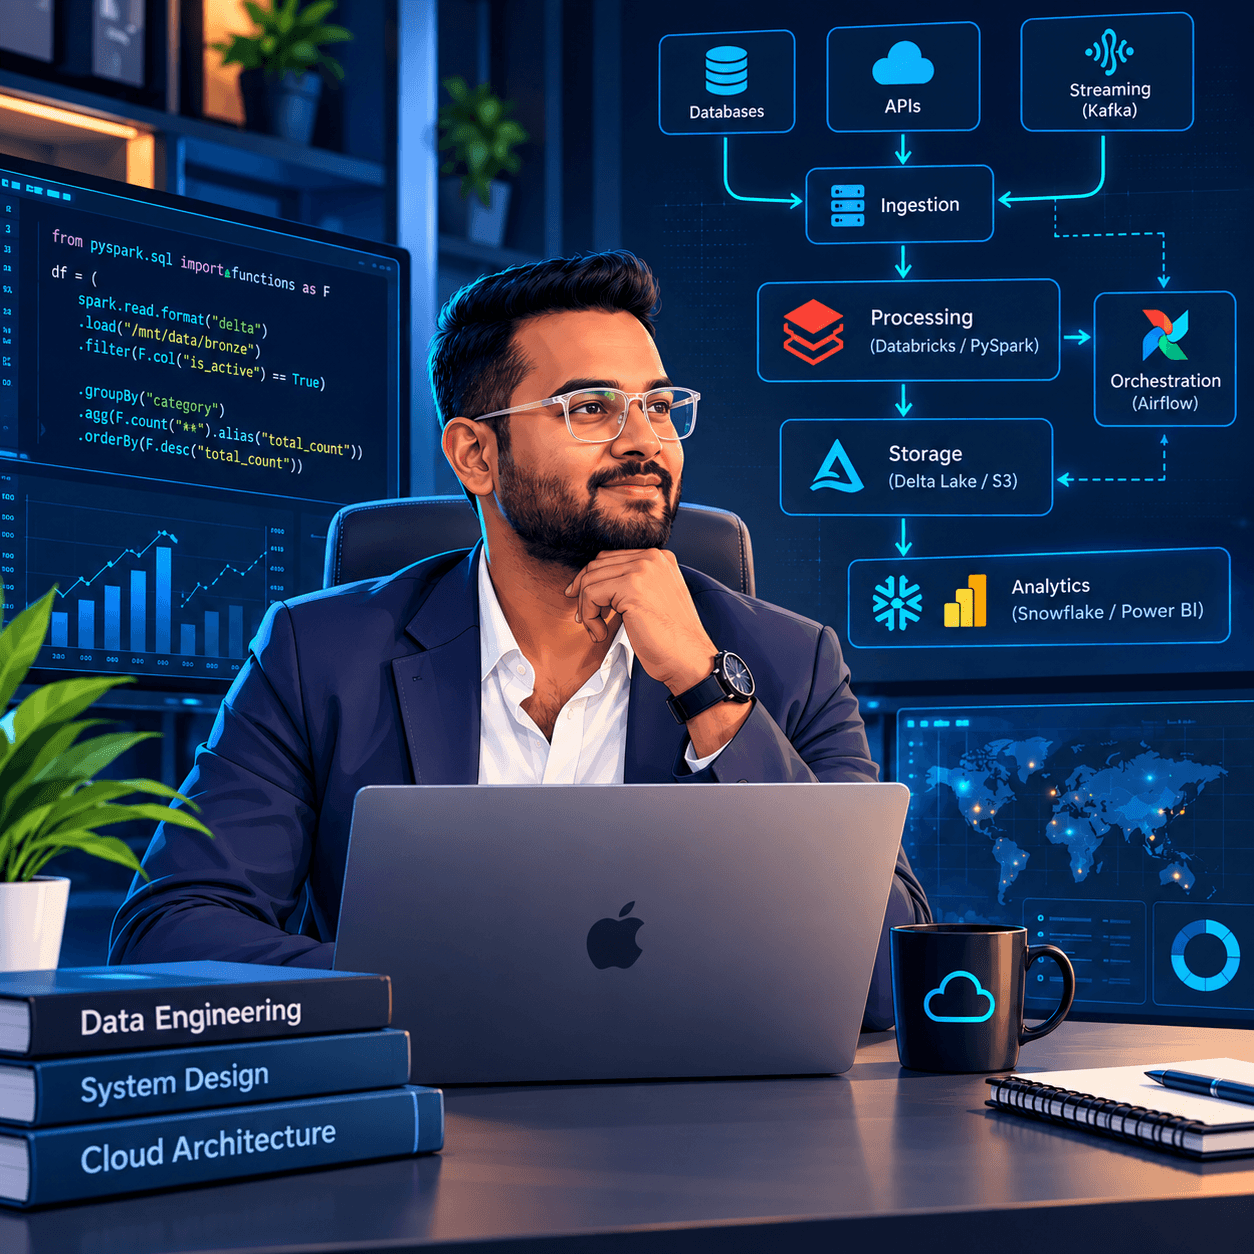
Databricks platform modernization
Modernizing orchestration, processing and storage together—moving Airflow and AWS EMR workflows into a governed Databricks platform.
Senior Data Engineer
I design and modernize production-grade data platforms using Databricks, PySpark, AWS and distributed data technologies—turning complex data into reliable systems built for scale.
I'm a Senior Data Engineer with 6+ years of experience designing, developing, migrating and optimizing enterprise data platforms. My work spans cloud-native ETL/ELT pipelines, distributed processing, workflow orchestration, data quality, streaming and platform modernization.
I work across Databricks, PySpark, AWS, Airflow, Snowflake and Kafka. The focus stays the same: systems that are maintainable, observable and reliable.

A progression from data integration to cloud platforms and Databricks modernization.
Modernizing orchestration, processing and storage together—moving Airflow and AWS EMR workflows into a governed Databricks platform.
Connecting cloud ingestion, distributed processing and analytics across batch and streaming workloads.
Building the foundations: integrating healthcare data through APIs and ETL, processing with Python, PySpark and SQL, and preparing data for reporting.
Engineering case studies spanning modernization, cloud data platforms and trusted analytical delivery.
Moving legacy Airflow and EMR workflows into Databricks-native orchestration, governed storage and repeatable PySpark processing.
Connecting ingestion, transformation and analytical access across AWS data services, from cloud storage to warehouse-ready data.
Event ingestion and continuous processing with Kafka, PySpark and Flink, with fault tolerance and observability in the design.
Repeatable source-to-target validation that protects platform migrations and makes data discrepancies visible.
Bringing operational data through engineering and warehousing into an analytical layer built for reporting.
The tools matter. How the system holds together matters more.
Repeatable movement from source to serving layer.
ExploreProcessing strategies that fit the workload.
ExploreConnected services. A coherent data platform.
ExploreChange the platform. Preserve the data contract.
ExploreTrust is built into every pipeline stage.
ExploreContinuous data. Deliberate delivery.
ExploreA successful job isn’t proof of correct data. Validation and reconciliation protect platform migrations and make production differences visible.
Data quality belongs inside the pipeline.
Illustrative validation flow
Understand the bottleneck before tuning the system. I approach Spark optimization through execution plans, partitioning, memory and data movement.
Align partitions with data distribution and downstream access patterns.
Inspect exchanges and reduce unnecessary movement between executors.
Choose joins from execution plans; broadcast only when the data fits.
Cache reused computations deliberately and release memory when finished.
Read logical and physical plans before changing transformations.
Balance executor memory and parallelism against the workload.
A connected view of ingestion, processing, validation and delivery.
Distribute processing with Databricks and Spark. Keep configuration separate from transformation logic.
Conceptual architecture. Orchestration coordinates the processing lifecycle.
A toolkit organized around the engineering work it supports.
Pipelines should be predictable, observable and recoverable.
Architecture should support increasing data volume without unnecessary redesign.
Validation and reconciliation belong inside the pipeline—not after it.
Measure bottlenecks before tuning Spark, storage or infrastructure.
Texas A&M University — Corpus Christi
Jawaharlal Nehru Technology University
I’m interested in opportunities involving scalable data platforms, cloud modernization, distributed processing and enterprise data engineering.
masterakshay04@gmail.com